RAVE Model by IRCAM: VST, Pretrained Models and Training
The RAVE model from IRCAM is a real-time neural audio model that turns any sound into the timbre it was trained on. You can play pretrained RAVE models in your DAW with Neutone FX or the RAVE VST, load them in Max/MSP or Pure Data with nn~, or train your own with the acids-rave Python package.
How to Use RAVE: Quick Start
| Goal | Tool | What you need |
|---|---|---|
| Play RAVE models in a DAW | Neutone FX (free VST/AU) | Any DAW. Pretrained models download inside the plugin. |
| Play RAVE models in a DAW | RAVE VST (beta) | An IRCAM Forum download. The source repository was archived in June 2023, and its Windows build is standalone only. |
| Use RAVE in Max/MSP or Pure Data | nn~ external | Max or Pd, plus a .ts model file |
| Download pretrained models | Official RAVE model list | Streaming .ts exports for nn~ |
| Train your own model | acids-rave on Python | An NVIDIA GPU with 5 to 32 GB of memory, a few hours of audio, and about 3 days |
To install nn~, download the latest release and extract it into Documents/Max [your version]/Packages/ for Max, or Documents/Pd/externals/ for Pure Data. Put your .ts models in the nn_tilde/models folder.

What Is IRCAM RAVE for Real-Time Audio Synthesis?
RAVE stands for Realtime Audio Variational autoEncoder. Released in late 2021 by researchers at IRCAM in Paris, it learns to encode sounds into a compact representation and then decode them back into audio. Think of it as teaching a computer to sketch what it hears, then redraw that sketch as a convincing imitation of the original sound.
It does this fast enough to run in real time inside your DAW or live performance setup.
Who Created RAVE and When?
RAVE was developed by Antoine Caillon, who now works for Google DeepMind, and Philippe Esling at IRCAM's ACIDS team in Paris.
The team had previously explored Google's DDSP (Differentiable Digital Signal Processing) model, showcasing it in March 2021, but wanted a more flexible model that could handle any type of sound, not just musical instruments.
Their goal was a model that runs on standard hardware while delivering studio-quality audio. They presented it in their 2021 paper, "RAVE: A variational autoencoder for fast and high-quality neural audio synthesis".
RAVE Architecture: How This Variational Autoencoder Works
RAVE is an autoencoder: a neural network that learns to compress data into a compact "latent space" and then decompress it back.
RAVE: two-stage training
Stage 1: Representation learning
Stage 2: Adversarial fine-tuning
Training diagram adapted from the original RAVE paper. Stage 1 trains the encoder and decoder using a multiband spectral loss. Stage 2 freezes the encoder, stops gradients through the latent code, and trains the decoder and discriminator. PQMF analysis and synthesis remain fixed.
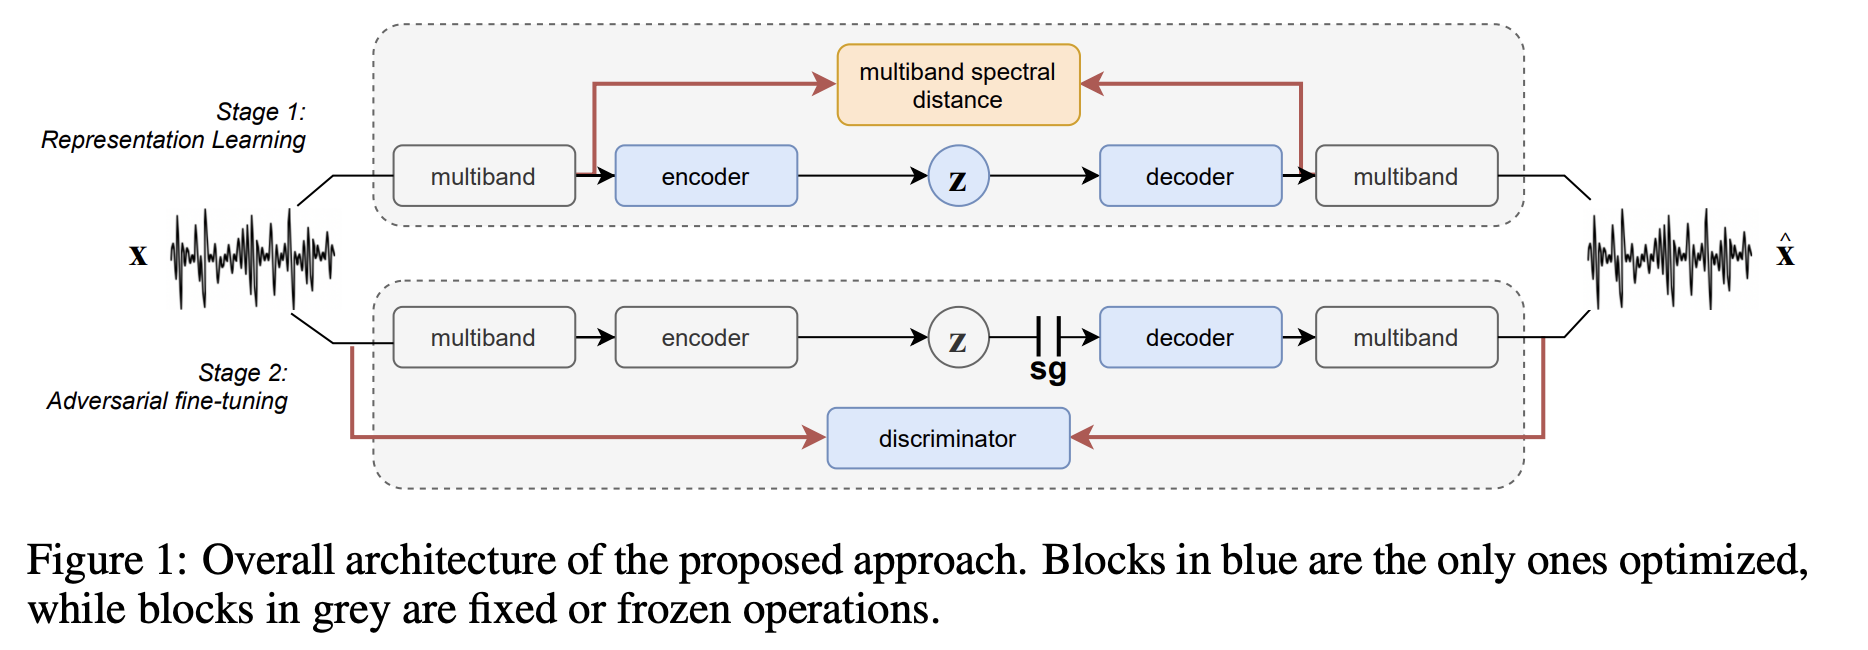
Original figure: RAVE: two-stage training.
How RAVE's Two-Stage Training Works
Think of it as training a musician in two phases:
-
Phase 1: Learning to Listen (Representation Learning)
- The encoder learns to squeeze audio into a compact set of numbers (the latent space)
- The decoder learns to reconstruct audio from those numbers
- Training uses a spectral loss, which compares the frequency content of the original and reconstructed audio
-
Phase 2: Learning to Improvise (Adversarial Fine-Tuning)
- The encoder is frozen (it already knows how to listen)
- A "discriminator" network is added: a critic that judges whether the reconstructed audio sounds real
- The decoder learns from this feedback to produce more convincing audio
Key Technical Components
- PQMF filters: RAVE splits audio into several frequency sub-bands before processing, which makes it more efficient
- Causal and non-causal modes: causal mode trades some quality for lower latency in live settings
- Multiple configurations: from the lightweight "raspberry" (runs on a Raspberry Pi) to the high-quality "v3"
For implementation details, see the official RAVE GitHub repository, which includes the configuration files and model definitions.

How to Train RAVE Models on Custom Audio Data?
Want a model that turns your voice into a saxophone? Training a RAVE model requires Python knowledge and a GPU. The official RAVE repository documents the full process.
Dataset Preparation Requirements
To train a RAVE model, you'll need:
- 2 to 3 hours of clean audio (more is better)
- Studio-quality recordings since RAVE learns everything, including noise and reverb
- Diverse sounds if you want versatility
To build a dataset from full mixes, isolate the instrument first with high quality AI stem splitting. Separation artifacts end up in the model too, so use the cleanest stems you can get. The stem splitting guide shows how to do it in Neural Analog.
Install RAVE and Prepare Your Dataset
Install PyTorch and TorchAudio for your GPU first, then RAVE. You also need FFmpeg; in a conda environment, install it with conda:
pip install acids-rave
conda install ffmpeg
Preprocessing converts your audio files into RAVE's dataset format:
rave preprocess --input_path /audio/folder --output_path /dataset/path --channels 1Use --channels 1 for mono or --channels 2 for stereo. Add --lazy to train directly on compressed files such as MP3, but expect a much higher CPU load during training. For all parameters, see the RAVE dataset preparation docs.
RAVE Training Process and Configurations
Start training with a configuration name:
rave train --config v2 --db_path /dataset/path --out_path /model/out --name my_model --channels 1Pick the configuration that fits your GPU. The minimum GPU memory comes from the official README:
| Config | Min. GPU memory | Use it for |
|---|---|---|
raspberry | 5 GB | Lightweight model for real time on a Raspberry Pi 4 |
onnx | 6 GB | Noiseless v1 for ONNX export |
v1 | 8 GB | The original continuous model |
v2_small | 8 GB | Timbre transfer on stationary sounds |
v2 | 16 GB | The improved continuous model and a good default |
discrete | 18 GB | A discrete model similar to SoundStream or EnCodec |
v3 | 32 GB | Highest quality, with style transfer (AdaIN) |
You can combine a configuration with options such as causal (lower latency) or noise. A community Colab notebook for RAVEv2, linked from the README, trains on Google's GPUs if you don't have one.
What to expect during training:
- Phase 1 (~1M steps): Audio quality starts rough and gradually improves
- Phase 2 (adversarial training): Quality improves sharply
- Total time: about 3 days on an RTX 3080 GPU
Community-contributed RAVE training notebooks walk through the process step by step.
Exporting RAVE Models for Real-Time Use
Export matters for real-time use. Use the --streaming flag to enable cached convolutions, which prevents clicking artifacts:
rave export --run /path/to/your/run --streamingThe result is a TorchScript .ts file that nn~ can load. For export parameters and troubleshooting, see the RAVE export docs.
RAVE Model Inference and Real-Time Usage Options
Don't want to wait 3 days for training? You can try pretrained RAVE models in several tools. They also load models you train yourself, and the FAQ on using a trained model in your DAW lists the plugin for each model type.
Neutone FX: Free VST/AU Plugin for RAVE Models
Neutone FX is a free VST/AU plugin that hosts RAVE models. It's the original Neutone plugin from 2022, now maintained as an open platform. Install it to load a collection of pretrained models directly in your DAW (Ableton, Logic, Reaper, and others).

RAVE VST by IRCAM (Beta, Archived)
IRCAM also released its own RAVE VST, with VST, AU, and standalone builds. It has two modes: reconstruction, which processes the audio coming from your DAW, and prior, which generates sound by moving through the latent space on its own. Its Model Explorer downloads pretrained models, and you can import your own if you export them with --stereo true.
The rave_vst repository was archived in June 2023, so expect no fixes. On Windows, only an experimental standalone build exists, and M1 Mac users must build it themselves. The developers recommend nn~ for real-time use instead.
Max/MSP and Pure Data Integration with nn~
For live performance, the nn~ external loads RAVE models directly in Max/MSP and Pure Data. It enables direct latent space manipulation and Adaptive Instance Normalization for style transfer. It also runs on embedded platforms like the Raspberry Pi for portable installations. The same boards run neural guitar amp plugins such as ToobAmp and Stompbox. If your board is an NVIDIA Jetson Nano, note that it has no analog audio output: add an I2S sound card such as the Raspiaudio Audio+ first.
RAVE Performance Limitations and Technical Caveats
Know these limitations before you rely on RAVE:
- Latency: Even in causal mode, expect noticeable delay, even on high-end Apple Silicon. That's fine in the studio, but test carefully before using RAVE as a live instrument.
- GPU acceleration: The model uses many small convolutions that are memory-bound rather than compute-bound, so it doesn't parallelize well. For real-time use, GPU overhead often outweighs the benefit unless you're batch-processing.
- Audio quality: RAVE can sound impressive, but it may not match the fidelity of traditional synthesis or of higher-end neural models such as diffusion-based ones.
- Difficult to train: Training a RAVE model takes machine learning and audio processing expertise, plus strong hardware.
RAVE Follow-Ups: Neutone Morpho and AFTER Model
Neutone Morpho: Commercial Evolution of RAVE (2024)
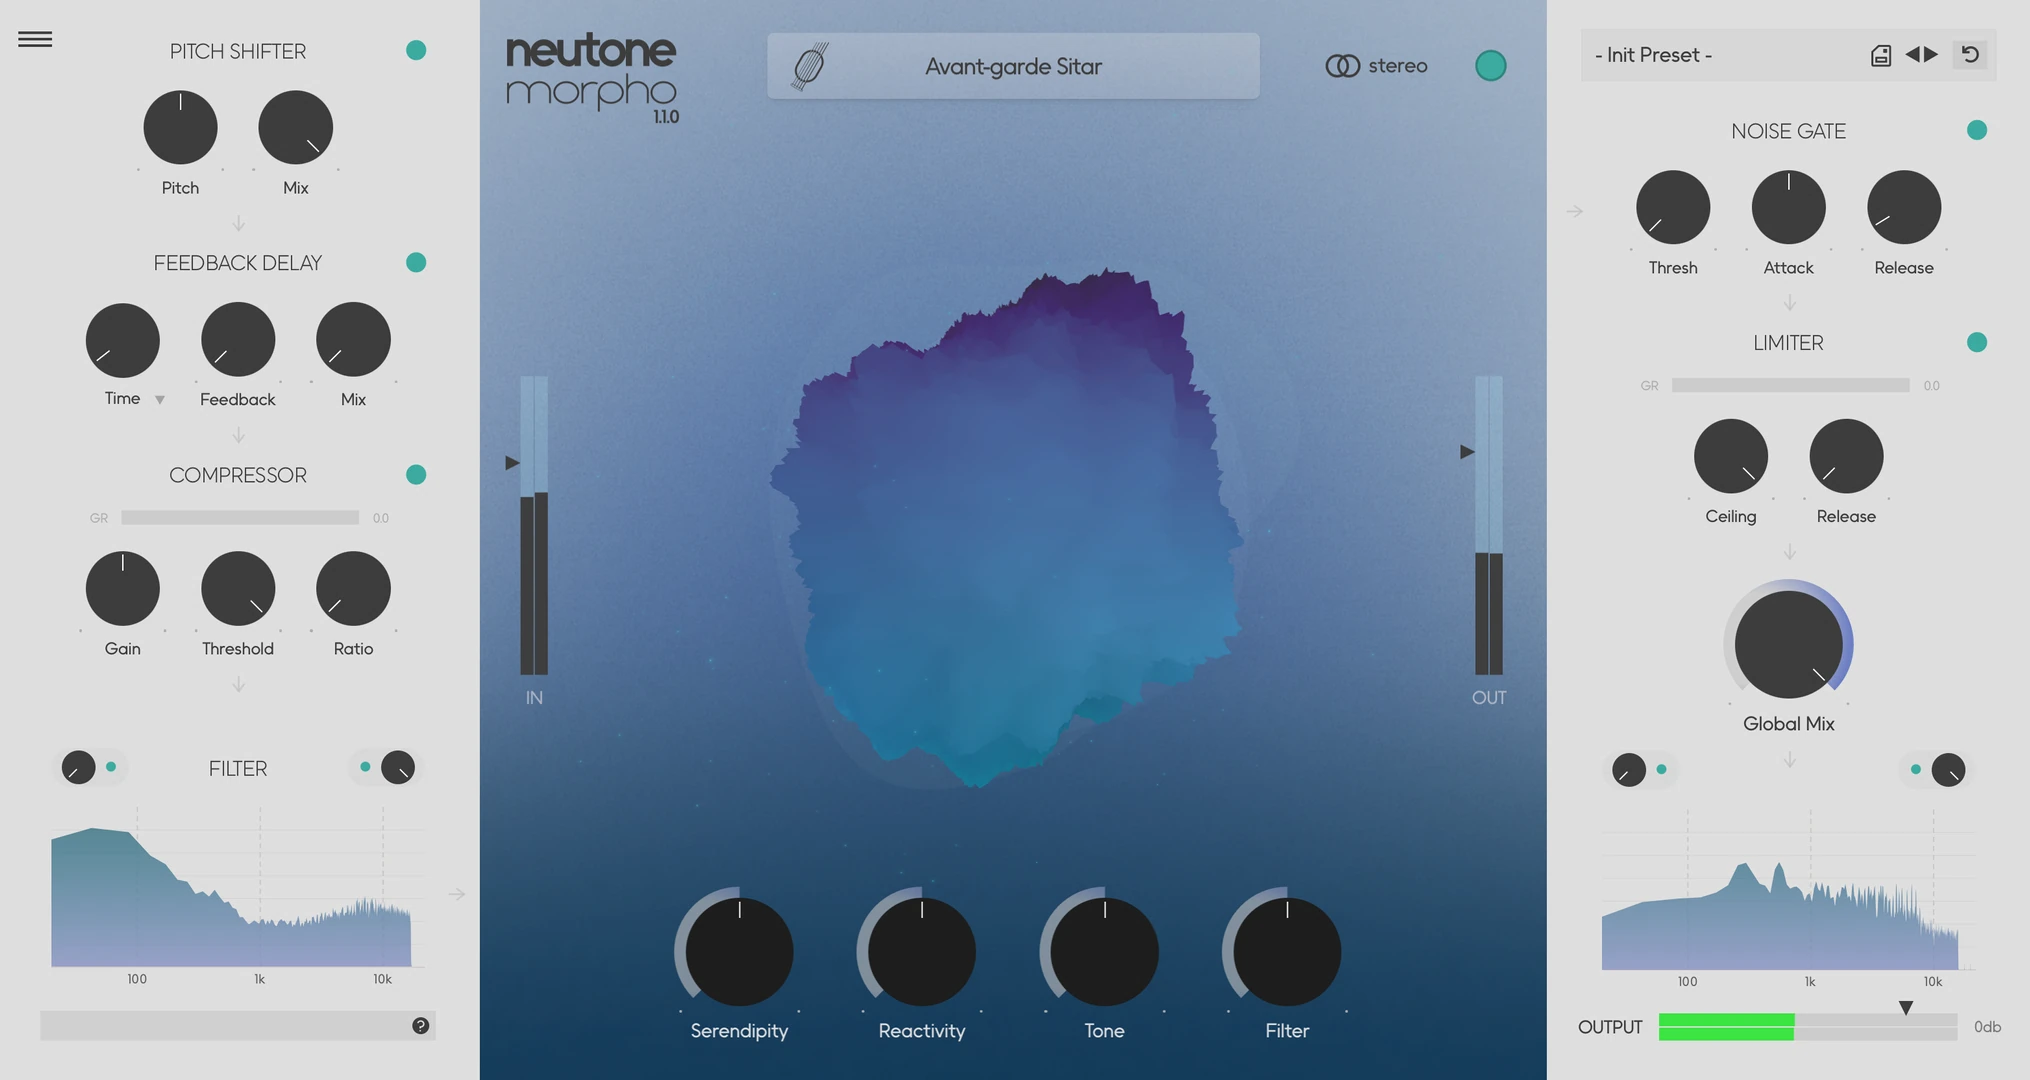
In February 2024, the Neutone team led by Nao Tokui released Morpho, a commercial successor to their free FX plugin. RAVE is the open-source research engine. Morpho packages similar technology into a polished product for musicians and producers, at the cost of flexibility.
AFTER Model: Diffusion-Based Alternative from IRCAM
The same IRCAM ACIDS team also released AFTER (Audio Features Transfer and Exploration in Real-time), a diffusion-based model. It aims to be more "tweakable", with real-time control over timbre like a traditional synthesizer.
To change the style of a whole song from a text prompt rather than one sound, AI remix keeps the vocal stem and regenerates the instrumental with Stable Audio 3.
RAVE FAQ
Where can I download pretrained RAVE models?
IRCAM lists streaming models on the official RAVE model page. Neutone FX and the RAVE VST can also download models from inside the plugin. Check each model's license before you use it in a commercial release.
How much audio do I need to train RAVE?
Plan for 2 to 3 hours of clean audio from a single source. RAVE learns everything in the recordings, including noise and room reverb. For DDSP and AFTER figures, see how much data you need to train a model.
Can I train RAVE on a Mac?
It is not a good fit. The UAL Creative Computing Institute RAVE guide asks for a CUDA-enabled NVIDIA GPU with at least 8 GB of memory and advises against macOS. Use a cloud GPU or the community Colab notebook instead.
Why does my RAVE model click in Max?
The model was exported without --streaming. Export it again with that flag.
RAVE or DDSP?
DDSP needs only about 10 minutes of audio but only models monophonic pitched instruments. RAVE handles any sound, including drums, voices, and textures, but needs hours of audio and days of training.